Statistical Validation for Time-Series Research
Educational concepts for evaluating time-series hypotheses, limiting overfitting, accounting for multiple tests, and communicating uncertainty.
A hypothesis can appear convincing when it is repeatedly adjusted and evaluated against the same observations. This is a general risk in time-series research: patterns may reflect the selection process or random variation rather than a relationship that will persist in new data.
This article introduces general statistical ideas for reducing those risks. The examples are educational and do not describe the data, strategy, research methodology, or implementation of any specific production or research system.
Respecting Time Order#
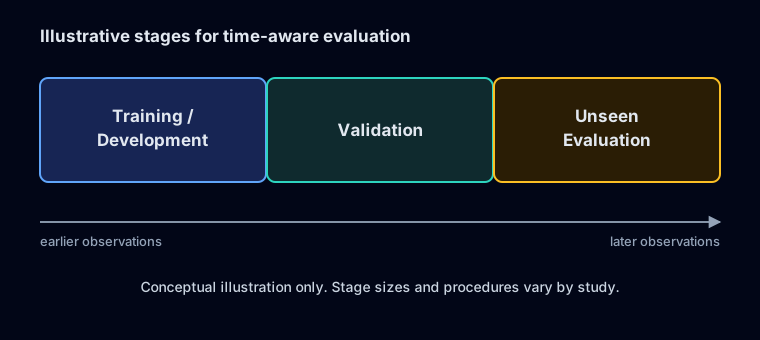
For data where order matters, evaluation should respect the timeline. Randomly mixing earlier and later observations can let information from the future influence model development. A conceptual workflow separates data by its role:
- Training or development data: Explore ideas and fit candidate models.
- Validation data: Compare candidate approaches and make development choices.
- Unseen evaluation data: Assess a finalized approach on observations not used to guide development.
Accounting for Multiple Comparisons#
When conducting $M$ independent tests at significance level $\alpha$, the chance of at least one false positive is $1 - (1 - \alpha)^M$. For example, 20 independent tests at $\alpha = 0.05$ produce a family-wise false-positive probability above 64%. The assumptions matter, but the example illustrates why a long search can make chance findings look persuasive.
Depending on the question, researchers may use procedures that control the family-wise error rate or the false discovery rate. These methods address different goals; neither replaces careful study design, transparent reporting, and independent evaluation.
Estimating Uncertainty#
Resampling methods such as the bootstrap can help estimate how sensitive a result is to variation in the observed sample. The resampling design should preserve relevant structure, such as temporal dependence, rather than assume observations can always be shuffled independently. Report uncertainty alongside point estimates and describe the assumptions behind it.
Time-aware evaluation, multiple-testing awareness, uncertainty estimates, and reproducible records are general research disciplines. The material here is an educational overview, not a description of OmniScreener or any other system's actual research implementation. For help designing data-intensive software or reviewing system architecture, see my Software Architecture Services or schedule an advisory call.
Production Case Studies & Capabilities
Explore how these engineering patterns are deployed in production systems and available through client engagements.
Software Architecture & System Design
Fast-moving teams frequently accrue hidden architectural liabilities: tangled domain logic, unmaintainable monoliths, or over-engineered microservices that paralyze development.
Related Technical Articles
Auditing AI-Generated Web Applications for Production Readiness with AI App Production Auditor
How to statically audit AI-scaffolded full-stack applications for configuration drift, local endpoint leaks, and deployment risks using the zero-dependency AI App Production Auditor CLI.
AI Coding Assistants: Where They Help and Where Engineering Judgment Still Matters
Where AI coding assistants excel, why syntactically valid code fails architectural scrutiny, and how professional engineers maintain software reliability.